Benchmarks & Comparisons
Choosing between AI models and tools is hard when every vendor claims victory. This hub settles it with AI model benchmarks and head-to-head comparisons: same prompts, same hardware, published methodology. Whether you are picking a local runner, a frontier API model, or a serving stack, start with the numbers here — not the marketing.
Local runners and serving stacks
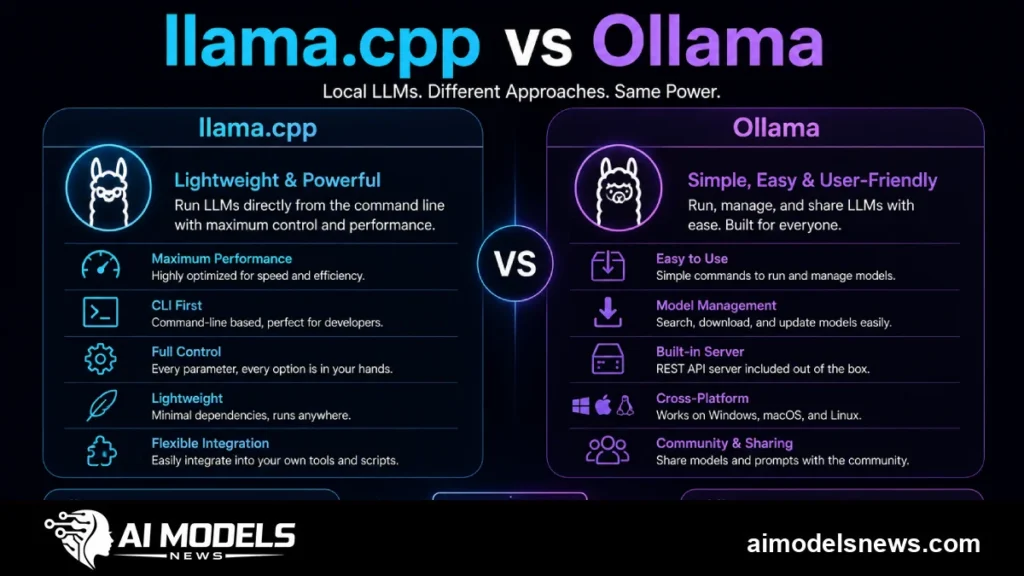
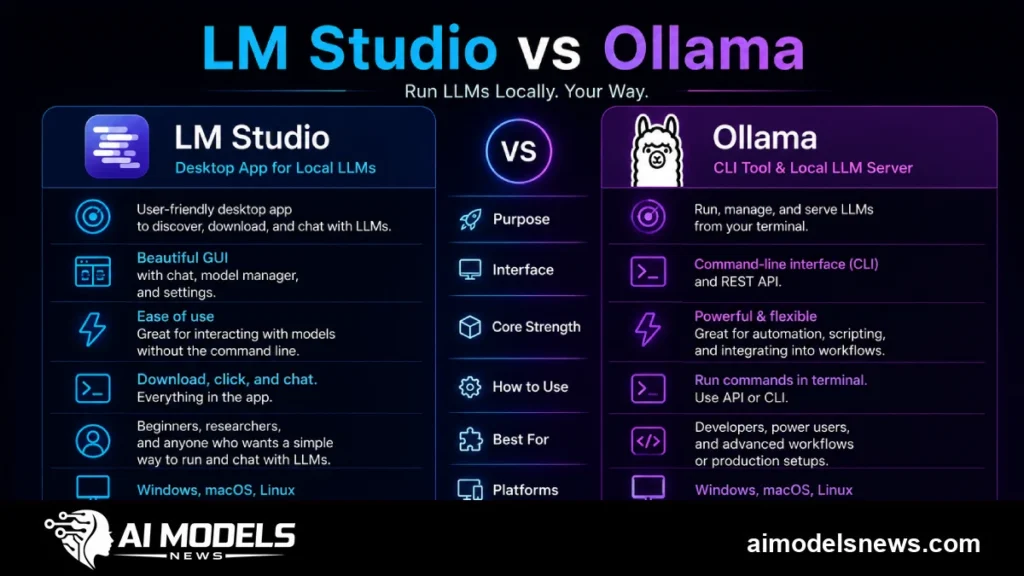
The local ecosystem splits into desktop apps, CLI runners, and production servers. Our LM Studio vs Ollama comparison covers the GUI-versus-CLI decision, while llama.cpp vs Ollama shows what the packaged convenience costs in raw performance. For teams moving to production, vLLM vs Ollama explains where single-user tooling ends and high-concurrency serving with PagedAttention begins. Desktop users should also see Jan vs LM Studio for the open-source, air-gapped alternative.
Frontier API models
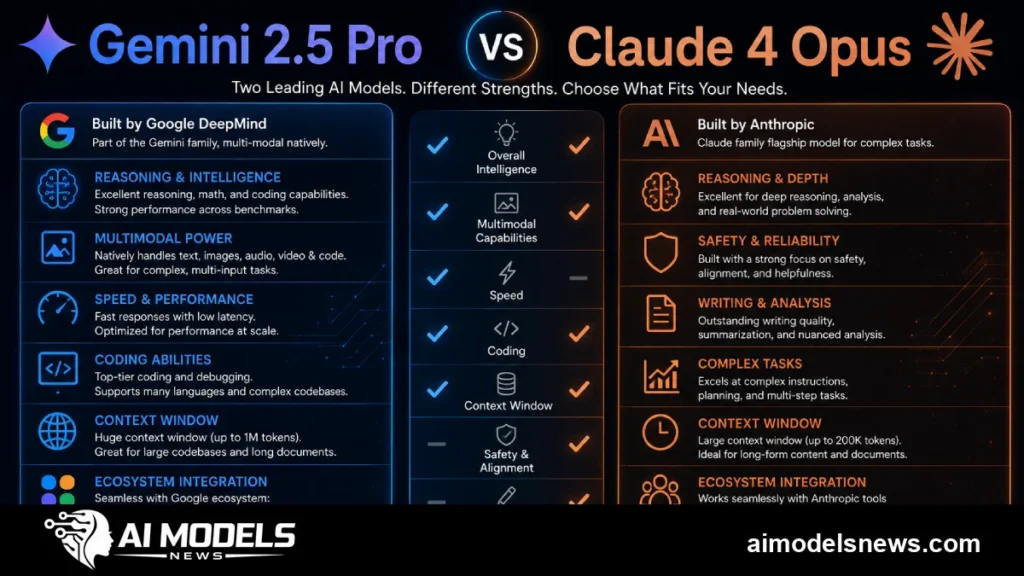
At the API tier the decision is about context windows, pricing, and reasoning depth. Gemini 2.5 Pro vs Claude 4 Opus compares context limits, pricing tiers, and complex coding performance. Within the Claude family, Claude Sonnet vs Opus answers the daily question: when is the fast, cheaper model enough, and when does deep reasoning pay for itself?
How we compare
Every comparison states its test conditions: hardware, quantization, prompt set, and pricing date. Prices and benchmark standings shift monthly in this field, so each article notes when its numbers were captured. If a result looks off on your own hardware, tell us — corrections are part of the method.