
Updated · Sources & corrections
In this guide
This page compares the named Gemini 2.5 Pro and Claude Opus 4 releases. It is not a ranking of the newest models. Vendor results describe their stated evaluation conditions and are not independent measurements by this publication.
This comparison covers context limits, API pricing tiers, coding and reasoning benchmarks, and the ecosystems around each model, so you can pick based on your workload rather than hype.
Gemini 2.5 Pro vs Claude Opus 4 at a glance
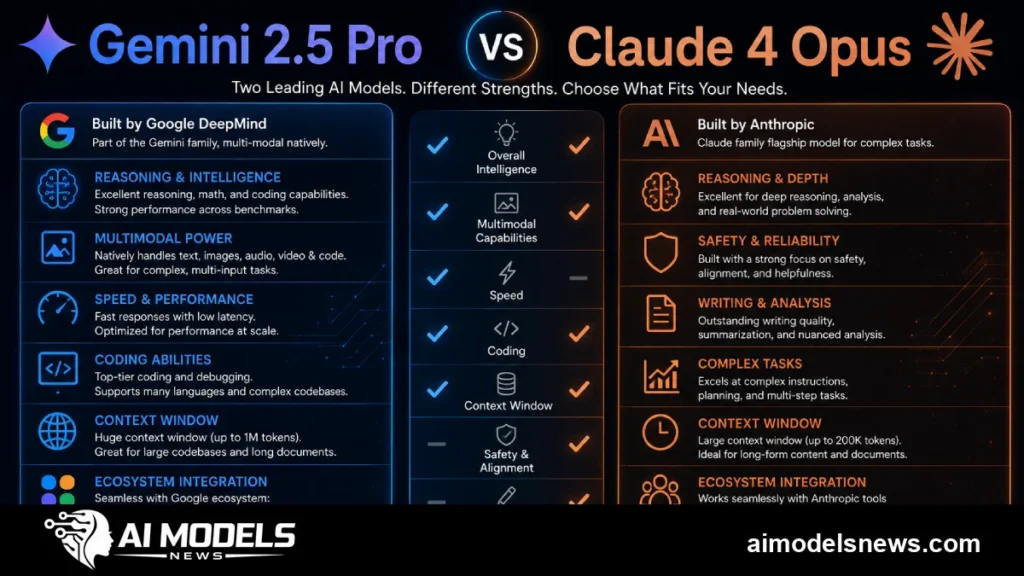
The table below summarizes the headline specs. Numbers are approximate, publicly reported figures and may shift as both vendors update tiers and limits.
| Spec | Gemini 2.5 Pro | Claude Opus 4 |
|---|---|---|
| Context window | Consult the exact model documentation | ~200K tokens |
| Max output | ~64K tokens | ~32K tokens |
| Key strengths | Huge context, multimodal, low cost | Coding, reasoning, agentic reliability |
| Main access points | AI Studio, Vertex AI, Gemini API | Anthropic API, Claude Code, Amazon Bedrock |
The pattern is clear: Google competes on scale and price, while Anthropic competes on per-task quality. Which trade-off matters depends entirely on what you’re building.
Context window and output limits
Gemini’s million-token advantage
Gemini 2.5 Pro ships with a context window of roughly one million tokens, with Google publicly targeting two million. In practice that means you can feed it entire codebases, hours of transcribed audio, or a shelf of PDFs in a single prompt.
Long-context recall on Gemini has historically been strong, though retrieval accuracy still degrades somewhat near the window’s edge. For most real workloads, though, it is the most generous generally available context on the market.
Claude’s smaller but steadier window
Claude Opus 4 offers around 200K tokens of context, a fifth of Gemini’s headline figure. Anthropic has focused more on reliability within that window than on raw size, and Claude models tend to behave predictably on long inputs.
Output limits also differ. Gemini can generate up to roughly 64K tokens in one response, while Opus 4 caps out around 32K — relevant if you generate entire files or long reports in a single pass.
API pricing tiers
Use the original vendor evaluation and current billing documentation for the exact release. Scores obtained with different agent scaffolding or test configurations should not be treated as a controlled comparison. This page does not report an independent matched run.
Consult the linked Google pricing page and the provider information for the exact Claude model. Historical launch prices and current account-specific costs should not be treated as interchangeable.
Both platforms offer cost levers worth knowing. Anthropic provides prompt caching and batch discounts that can cut effective costs substantially, and Google’s batch mode offers similar savings on non-urgent jobs.
If Opus 4’s price is hard to justify, it’s worth reading our Claude Sonnet vs Opus breakdown — Sonnet delivers much of the coding quality at a fraction of the cost.
Complex coding benchmarks
What the public numbers suggest
On competition-style programming tests such as LiveCodeBench, both models trade positions across versions and dates. Treat any single number as a snapshot, not a verdict — benchmark results vary significantly by task, prompt format, and evaluation harness.
How they differ in practice
Claude Opus 4 is widely regarded as the steadier pair programmer: it plans before editing, explains its changes, and rarely breaks unrelated code. Developers frequently describe its edits as “merge-ready” more often than rivals.
Gemini 2.5 Pro counters with context. It can hold an entire repository in memory and answer cross-file questions without retrieval plumbing, which partially offsets its per-edit disadvantage on very large projects.
A minimal API call to each looks like this:
curl https://generativelanguage.googleapis.com/v1beta/models/gemini-2.5-pro:generateContent
  -H "x-goog-api-key: $GEMINI_API_KEY"
  -H "Content-Type: application/json"
  -d '{"contents":[{"parts":[{"text":"Explain quicksort"}]}]}'
curl https://api.anthropic.com/v1/messages
-H "x-api-key: $ANTHROPIC_API_KEY"
-H "anthropic-version: 2023-06-01"
-H "Content-Type: application/json"
-d '{"model":"claude-opus-4-20250514","max_tokens":1024,"messages":[{"role":"user","content":"Explain quicksort"}]}'Reasoning behavior
Both models “think” before answering, but they expose it differently. Gemini 2.5 Pro uses a thinking budget you can dial up or down, letting you trade latency and cost for deeper reasoning on hard problems.
Claude Opus 4 offers extended thinking with a similar budget mechanism, and Anthropic summarizes the chain of thought in the response. On math and science benchmarks like GPQA and AIME-style problems, both models score in the same elite band, with leads swapping between revisions.
The qualitative difference: Opus tends to be more cautious and literal about instructions, while Gemini is sometimes more creative but more willing to take shortcuts. For compliance-sensitive work, Claude’s conservatism is often a feature.
Long-document analysis
This is Gemini 2.5 Pro’s home turf. Legal discovery sets, financial filings, research literature reviews, and full-book summarization all fit inside its context without chunking, embeddings, or a vector database.
Claude Opus 4 handles long documents well within its 200K window and is often praised for nuanced, well-structured summaries. But anything larger forces you into retrieval-augmented pipelines, which adds engineering complexity and can lose cross-document connections.
A practical rule: if your corpus routinely exceeds a few hundred pages, Gemini’s context window removes entire layers of infrastructure. If your documents fit in 200K tokens, Claude’s analytical polish may matter more than raw capacity.
Agentic tool use
Agentic workloads — where the model calls tools, runs commands, and iterates over hours — are Anthropic’s stated focus for Opus 4. It was designed to sustain long-running tasks, follow multi-step plans, and recover gracefully from tool errors.
Gemini 2.5 Pro supports function calling and code execution natively and performs competently in agent loops. Its advantage again is context: an agent that never has to compact its memory loses less state over long runs.
For terminal-based coding agents specifically, see our Gemini CLI vs Claude Code comparison, which tests both vendors’ agent harnesses on real repositories.
Ecosystem: Google vs Anthropic
Google AI Studio and Vertex AI
Gemini 2.5 Pro is available through Google AI Studio for quick prototyping and the Gemini API for production. Enterprise deployments typically run through Vertex AI, which adds data residency, VPC controls, and integration with the rest of Google Cloud.
The free tier in AI Studio is generous enough for serious experimentation. Tight integration with Workspace, BigQuery, and Android makes Gemini the path of least resistance if you’re already in Google’s orbit.
Anthropic API and Claude Code
Anthropic offers Opus 4 through its own API, Amazon Bedrock, and Google Vertex AI — notably, you can run Claude inside Google Cloud too. The API is clean, well documented, and supports prompt caching, batching, and citations.
Claude Code, Anthropic’s terminal agent, has become a genuine ecosystem draw on its own. Many teams choose Opus 4 specifically because Claude Code’s tooling, memory files, and MCP support make it the most productive agentic coding environment available today.
Which should you choose?
- Choose Gemini 2.5 Pro if you need huge context, multimodal inputs (video, audio, images), or high-volume workloads where a 5–10x price gap is decisive.
- Choose Claude Opus 4 if your priority is complex code edits, long agentic runs, careful instruction following, or you rely on Claude Code.
- Consider both: many teams route bulk analysis through Gemini and reserve Opus for hard coding and final review.
Also remember that benchmarks are directional, not absolute. Always run a small eval on your own data before committing — a weekend of testing beats a month of regret.
Bottom line
In the gemini 2.5 pro vs claude 4 opus matchup there is no universal winner, only better fits. Gemini 2.5 Pro dominates on context size and cost; Claude Opus 4 leads on coding craftsmanship and agentic reliability.
If budget and document scale define your workload, start with Gemini. If correctness and agent quality define it, Opus 4 earns its premium. Either way, both are frontier models that would have seemed impossible two years ago.
Sources and verification scope
This article distinguishes documented features and vendor-reported results from independent testing. No original head-to-head benchmark dataset is published for this page; hardware-memory figures retained in the guide are estimates, not measured guarantees.
Editorial update, 21 October 2026: source references and verification scope added; identified command, feature or wording errors corrected. Read our sourcing and correction policy.